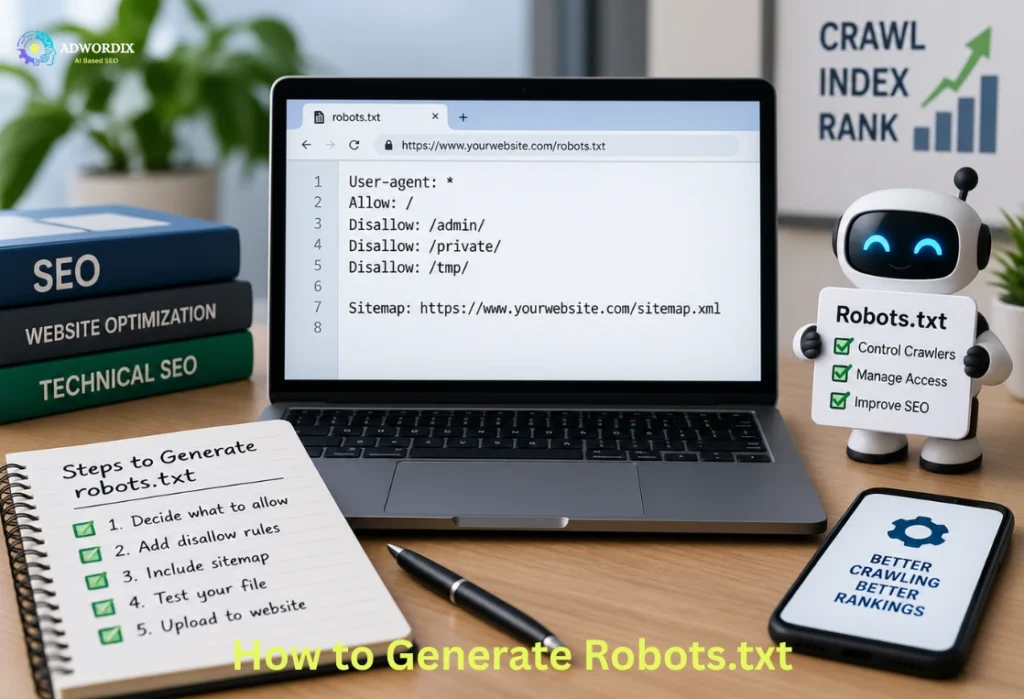
How to Generate Robots.txt: Step-by-Step Guide
Search engines need clear instructions to crawl your website efficiently. A well-configured robots.txt file helps guide crawlers away from unnecessary areas while keeping your important pages accessible.
To generate a robots.txt file, create a plain-text file named robots.txt, add relevant User-agent, Disallow, and Allow rules, include your XML sitemap, and upload the file to your website’s root directory.
But creating the file is only half the job. A wrong robots.txt disallow rule can block important pages, while using robots.txt to hide content from search results can lead to an “indexed though blocked by robots.txt” issue.
This guide shows you how to generate robots.txt, write the right rules, check whether it is working, and avoid common SEO mistakes.
What is a Robots.txt File?
A robots.txt file is a plain-text file placed in your website’s root folder. It acts as an instruction manual for automated web crawlers (like Googlebot or Bingbot), communicating which areas of your site they can or cannot crawl.
What Does Robots.txt Do?
Robots.txt manages crawler traffic to keep your server running smoothly and helps search engines discover important content efficiently:
- Controls Crawler Access: Tells bots which directory paths or specific URLs they are allowed to crawl.
- Manages Server Load: Prevents crawlers from overwhelming your server with requests for non-essential pages.
- Optimizes Crawl Budget: Ensures search bots spend time crawling your valuable pages rather than internal search results or duplicate parameters.
- Points to Sitemaps: Provides bots with a direct reference to your XML sitemap location.
SEO in digital marketing is mostly about making the site crawlable, and Robots.txt does the opposite while complementing the strategies to avoid exhausting the crawl budget.
What Robots.txt Does Not Do?
Misunderstanding what a robots.txt file does can lead to indexing mistakes. Here is what the file cannot do:
- It Does Not Guarantee Removal from Search: Google specifically notes that a URL blocked by robots.txt can still appear in search results if discovered through external links.
- It Does Not Replace a Noindex Tag: Disallowing a page prevents crawlers from reading it, but it does not tell them to drop an existing index entry.
- It Is Not a Security Wall: Web crawlers can ignore robots.txt instructions. It will not stop unauthorized users or malicious bots from visiting secret URLs.
- It Does Not Restrict Human Visitors: Human users navigating through a browser can still access disallowed pages directly.
How to Generate a Robots.txt File?
Creating your file requires just a few straightforward steps. Follow this process to set up your rules correctly.
Step 1: Create File ──► Step 2: Add Directives ──► Step 3: Add Sitemap ──► Step 4: Upload to Root
Step 1: Create a Plain Text File
Open a basic text editor such as Notepad (Windows) or TextEdit (Mac).
- Name the file exactly robots.txt (lowercase only).
- Set file encoding to UTF-8.
- Do not use rich-text editors like Microsoft Word, as they add hidden formatting characters that break crawler syntax.
Step 2: Add Your Crawler Rules
At its core, a robots.txt file uses basic syntax blocks containing two main components: a targeted crawler (User-agent) and a rule (Disallow or Allow).
Plaintext
User-agent: *
Disallow:
Step 3: Add the Rules You Need
Here are common configurations used across different site types:
- Allow All Crawlers Access:
Plaintext
User-agent: *
Disallow:
- Block a Specific Directory:
Plaintext
User-agent: *
Disallow: /private/
- Block a Specific Page Path:
Plaintext
User-agent: *
Disallow: /example-page/
- Allow a Specific File Within a Blocked Folder:
Plaintext
User-agent: *
Disallow: /private/
Allow: /private/public-page/
Search engines like Google officially support directives including User-agent, Disallow, Allow, and Sitemap.
Step 4: Add Your Sitemap
Adding a direct path to your XML sitemap helps search bots locate your primary content URLs faster.
Plaintext
Sitemap: https://example.com/sitemap.xml
File Type | Core Purpose | Directive Nature |
Robots.txt | Tells crawlers which paths they may or may not crawl | Mandatory instruction for compliant bots |
XML Sitemap | Lists the preferred URLs you want search engines to discover | Optional hint; does not guarantee crawling |
Step 5: Save and Upload the File
Save your file and upload it to the root directory of your web hosting account (often named public_html or www).
The file must be publicly accessible at the root level of your domain:
[https://example.com/robots.txt](https://example.com/robots.txt)
Note: Placing the file in a subdirectory like [example.com/blog/robots.txt](https://example.com/blog/robots.txt) will cause search engines to ignore it completely.
Step 6: Test Your Robots.txt File
After uploading, confirm that the file is working properly:
- Visit [https://yourdomain.com/robots.txt](https://yourdomain.com/robots.txt) in a web browser to verify it loads as plain text.
- Check for syntax errors, missing slashes, or typos in directive names.
- Use Google Search Console’s robots.txt report to confirm that Googlebot can fetch the file without errors.
How to Write Robots.txt Rules Correctly
Writing clean syntax prevents accidental blocks on important site sections.
Understanding User Agents
The User-agent directive specifies which search engine bot a rule applies to.
- User-agent: * targets all automated web crawlers.
- User-agent: Googlebot targets Google’s primary web crawler specifically.
Plaintext
# Blocks Bingbot from the search folder while allowing Googlebot
User-agent: Bingbot
Disallow: /search/
User-agent: Googlebot
Disallow:
Understanding Disallow
The Disallow rule tells targeted crawlers not to request specific path strings.
Plaintext
# Blocks access to any URL starting with /folder/
Disallow: /folder/
Common uses for Disallow include:
- Administrative dashboards (/admin/, /wp-admin/)
- Internal search result pages (/search?)
- Temporary staging or testing paths (/temp/)
- E-commerce shopping carts or checkout flows (/cart/, /checkout/)
Understanding Allow
The Allow directive overrides a broader Disallow rule for a specific sub-path, letting you open a single resource inside a blocked folder.
Plaintext
Disallow: /media/
Allow: /media/open-guide.pdf
Using Wildcards Carefully
Robots.txt supports pattern matching using special characters:
- * matches any sequence of characters.
- $ anchors the end of a URL string.
Plaintext
# Block all URLs ending in .pdf
Disallow: /*.pdf$
Robots.txt Comments
Add comments using the # symbol. Anything following # on that line is ignored by search engine crawlers, making your file easier to maintain.
Plaintext
# Block internal staging directories from all crawlers
User-agent: *
Disallow: /staging/
Robots.txt Setup for Different Websites
Different website architectures require distinct crawling rules to optimize performance.
Robots.txt for WordPress
WordPress generates a dynamic virtual robots.txt file automatically. However, editing it via an SEO plugin or uploading a physical file helps restrict access to unnecessary administrative areas.
Plaintext
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Sitemap: https://example.com/wp-sitemap.xml
Robots.txt for a New Website
For a new website, keep your file simple. Avoid overcomplicating rules before your content is published, and make sure you don’t accidentally leave a staging block active when going live.
Robots.txt for E-commerce Websites
E-commerce stores often generate thousands of duplicate or dynamic URLs through filters, sorting options, and search parameters. Restricting these paths saves crawl budget for primary product pages.
Plaintext
User-agent: *
Disallow: /checkout/
Disallow: /cart/
Disallow: /*?sort=
Disallow: /*&filter=
Robots.txt for Blogs
Blogs benefit from keeping admin paths and tag filter duplicates out of the crawl path while keeping all main category and article paths completely open.
Robots.txt for Large Websites
Publishers or enterprise sites with millions of URLs must manage crawl efficiency carefully. Restrict non-essential dynamic paths and organize rules by subdirectory to keep crawler resources focused on key content.
Robots.txt for Subdomains
Robots.txt rules apply only to the specific protocol, host, and port where the file lives. A file at [example.com/robots.txt](https://example.com/robots.txt) does not control crawling on [subdomain.example.com/robots.txt](https://subdomain.example.com/robots.txt). You must upload a separate file to each subdomain.
How to See the Robots.txt of a Website
To inspect any site’s crawling rules, open your browser and append /robots.txt to the root domain.
https://www.example.com/robots.txt
Plaintext
# Example output viewed in a browser
User-agent: *
Disallow: /admin/
Allow: /
Sitemap: https://www.example.com/sitemap.xml
What to Look For in the File
When examining a live file, check for these core directives:
- User-agent lines: Identifies which bots are being given instructions.
- Disallow rules: Shows which paths crawlers are restricted from visiting.
- Allow exceptions: Shows specific pages opened within disallowed folders.
- Sitemap locations: Lists official XML sitemap files.
How to Check Rules for a Specific URL
To verify if a URL is blocked, locate the rule block matching your user agent (or User-agent: *), then check if the URL path matches any listed Disallow entries.
How to Check If Robots.txt is Working
Regular testing ensures your site’s crawling instructions remain accurate.
1. Check That the File Loads
Open [https://example.com/robots.txt](https://example.com/robots.txt) in an incognito browser window. Confirm it returns a 200 OK HTTP status code and displays plain text without HTML tags.
2. Test Important URLs
Verify that key pages are open to crawlers:
- Your homepage
- Core service and product pages
- Blog posts and primary categories
- Resource downloads
3. Review Google Search Console
Use the URL Inspection Tool inside Google Search Console. Paste a URL and review the “Coverage” section to confirm whether Googlebot can crawl the page cleanly.
4. Check for Accidental Blocking
Watch out for broad disallow statements that can accidentally block your entire site:
Plaintext
# DANGER: This blocks ALL search engines from crawling the entire website
User-agent: *
Disallow: /
What Does “Blocked by Robots.txt” Mean?
“Blocked by robots.txt” means a search engine crawler tried to access a URL but found a Disallow rule telling it not to crawl that page or path.
Robots.txt vs. Noindex: Know the Difference
Robots.txt | Noindex |
🚫 Stops crawlers from accessing a URL | 🚫 Tells search engines not to index a page |
The crawler cannot read the page content | The crawler can access and read the page |
Does not guarantee removal from search results | Designed to prevent indexing |
Key takeaway: Being blocked from crawling does not mean being removed from Google. A blocked URL can still appear in search results if Google discovers it through other sources.
Why Can a Blocked URL Still Appear in a Search?
If external websites link to a URL blocked by your robots.txt file, search engines can still index the URL based on anchor text and surrounding context. However, because the bot cannot crawl the page directly, it won’t be able to read your page content or meta tags, even if your content is SEO-friendly.
Why Is My Page Indexed Though Blocked by Robots.txt?
When a page displays the status “Indexed, though blocked by robots.txt,” search engines have indexed the URL without crawling its underlying content.
External Link Found ──► URL Added to Queue ──► Robots.txt Blocks Crawl ──► Search Engine Indexes URL Shell
Because the crawler was disallowed from visiting the page, it could not read any on-page directives, including a noindex tag.
How Do I Prevent a Page From Being Indexed?
If your goal is to completely remove a page from search results, do not block it in robots.txt. Follow these steps instead:
- Remove the Disallow Rule: Ensure crawlers can access the page.
- Add a Noindex Tag: Place it <meta name=”robots” content=”noindex”> in the page’s <head> section.
- Wait for Recrawling: Allow search bots to visit the page, read the noindex tag, and remove the URL from search results.
- Password Protect (Optional): Restrict access using user authentication if the content contains private data.
How Does Robots.txt Affect SEO?
While robots.txt does not boost keyword rankings directly, managing crawl access is an important part of technical site health.
- Saves Crawl Budget: Restricts crawlers from spending resources on thin or duplicate URL variations.
- Protects Sensitive Paths: Keeps staging folders, account pages, and cart paths out of search engine discovery queues.
- Optimizes Resource Usage: Ensures search bots spend their allotted time indexing your core business offerings.
Common Robots.txt Mistakes to Avoid
- Accidentally Disallowing the Root (Disallow: /): Blocks search crawlers from accessing your entire website.
- Placing the File in a Subdirectory: Uploading the file anywhere other than the root directory (/robots.txt) makes it invalid.
- Blocking CSS and JavaScript: Restricting asset files prevents search bots from rendering your pages correctly, which can hurt your rankings.
- Using Robots.txt for Sensitive Security: Leaving private URL paths inside a public file reveals those paths to anyone who views it.
- Attempting Noindex via Robots.txt: Relying on Disallow rules to remove pages from search results usually fails.
Robots.txt Best Practices for SEO
- Keep Rules Simple: Use clear, straightforward paths to avoid rule conflicts.
- Block Only What Is Necessary: Don’t disallow paths unless you have a specific reason to restrict crawling.
- Include Your Sitemap URL: Use an absolute URL reference (https://example.com/sitemap.xml) at the end of your file.
- Review Rules After Migrations: Recheck your file whenever updating your CMS, changing domain structures, or pushing code updates.
Robots.txt vs. Noindex: Which Should You Use?
Choosing the right tool depends on whether you want to control crawler access or search result visibility.
Goal | Recommended Approach | Correct Tool |
Control Crawler Traffic | Prevent bots from accessing specific directories | robots.txt Disallow |
Remove Page from Search | Allow crawling so bots read page-level tags | <meta name=”robots” content=”noindex”> |
Restrict Private Access | Require user credentials to view content | Server Authentication |
Guide Search Discovery | Provide a list of preferred URLs | XML Sitemap |
Aligning these technical choices with a clear understanding of search intent optimization ensures that your indexable content matches what searchers are looking for.
A Simple Robots.txt Example
Here is a balanced template suitable for most standard websites:
Plaintext
User-agent: *
Disallow: /admin/
Disallow: /private/
Disallow: /search/
Allow: /private/public-page/
Sitemap: https://example.com/sitemap.xml
Directive Line | Purpose |
User-agent: * | Applies rules to all web crawlers. |
Disallow: /admin/ | Blocks crawling of administrative dashboard paths. |
Disallow: /private/ | Blocks crawling of the specified private folder. |
Allow: /private/public-page/ | Opens a specific file inside the blocked /private/ folder. |
Sitemap: https://… | Directs crawlers to the site’s XML sitemap file. |
There is no single “perfect” setup. Adjust your directives based on your CMS, URL structure, and server capacity.
Robots.txt Checklist Before You Publish
- The file is named robots.txt (all lowercase).
- The file is saved in plain text format using UTF-8 encoding.
- The file is uploaded to the root directory ([example.com/robots.txt](https://example.com/robots.txt)).
- User agent: Targets are defined accurately.
- Important content pages, CSS, and JS assets are not blocked.
- The absolute URL path to the XML sitemap is included.
- File loads with a 200 OK status code in a web browser.
- The file has been verified using Google Search Console tools.
Conclusion
A well-configured robots.txt file helps search engines crawl your website efficiently by clearly defining which areas they can and cannot access. To generate robots.txt correctly, use simple User-agent, Allow, and Disallow rules; add your XML sitemap; place the file at your domain root; and test it to ensure everything works as intended.
Just as keyword research for SEO helps you identify the searches and topics worth targeting, robots.txt helps search engines focus their crawling on the pages that matter most. It does not control rankings or replace indexing controls, but when set up correctly, it can help manage crawl budget, avoid unnecessary crawling, and keep your technical SEO foundation healthy.
Table of Contents
Ready to
Work with us?
Author Box
Sakshi Jaiswal
Sakshi Jaiswal, a digital marketing expert, shares cutting-edge insights and strategies. She enjoys exploring new marketing technologies and tools.
Frequently Asked Questions
A website can work without a robots.txt file. In that case, search engine crawlers generally have no robots.txt rules to follow and can crawl pages that are otherwise accessible. A robots.txt file becomes useful when you need to guide crawler access to specific areas of a website.
Yes. A robots.txt file can block Googlebot from crawling specific URLs, directories, or even the entire website. However, blocking Googlebot is different from preventing a page from appearing in search results, so robots.txt should be used carefully.
No. Robots.txt is not a reliable way to remove a page from Google Search. If a page should not be indexed, use appropriate indexing controls, such as a noindex directive where applicable, rather than relying only on a robots.txt disallow rule.
There is no fixed schedule for updating robots.txt. Review it whenever you change your website structure, add new sections, migrate platforms, introduce new crawl rules, or discover that important pages are being blocked.
Yes. Robots.txt rules can restrict crawlers from accessing specific file types or directories. However, if your goal is to control whether a resource appears in search results, choose the appropriate indexing or access-control method rather than using robots.txt alone.
No. A small website may not need complex robots.txt rules at all. A simple file can be enough when specific crawl instructions are required, while large, dynamic, or e-commerce websites may need more carefully planned rules.
A given host and protocol use one applicable robots.txt file at the root, such as https://example.com/robots.txt. You should not create separate robots.txt files for different website sections.
Not directly. Robots.txt is a crawl-management tool, not a ranking factor. Its SEO value comes from helping search engines access the right parts of your website while avoiding unnecessary crawling of areas you do not want crawled.
First, check the current robots.txt file and identify the rule affecting the URL. Then correct or remove the unintended disallow rule, verify that the important page is crawlable, and monitor crawling and indexing after the change.
No. DA is a third-party SEO metric, not a complete measure of whether a website is trustworthy. Website trust also depends on factors such as accurate information, transparency, user experience, security, reputation, and the quality of the content and business behind the site.